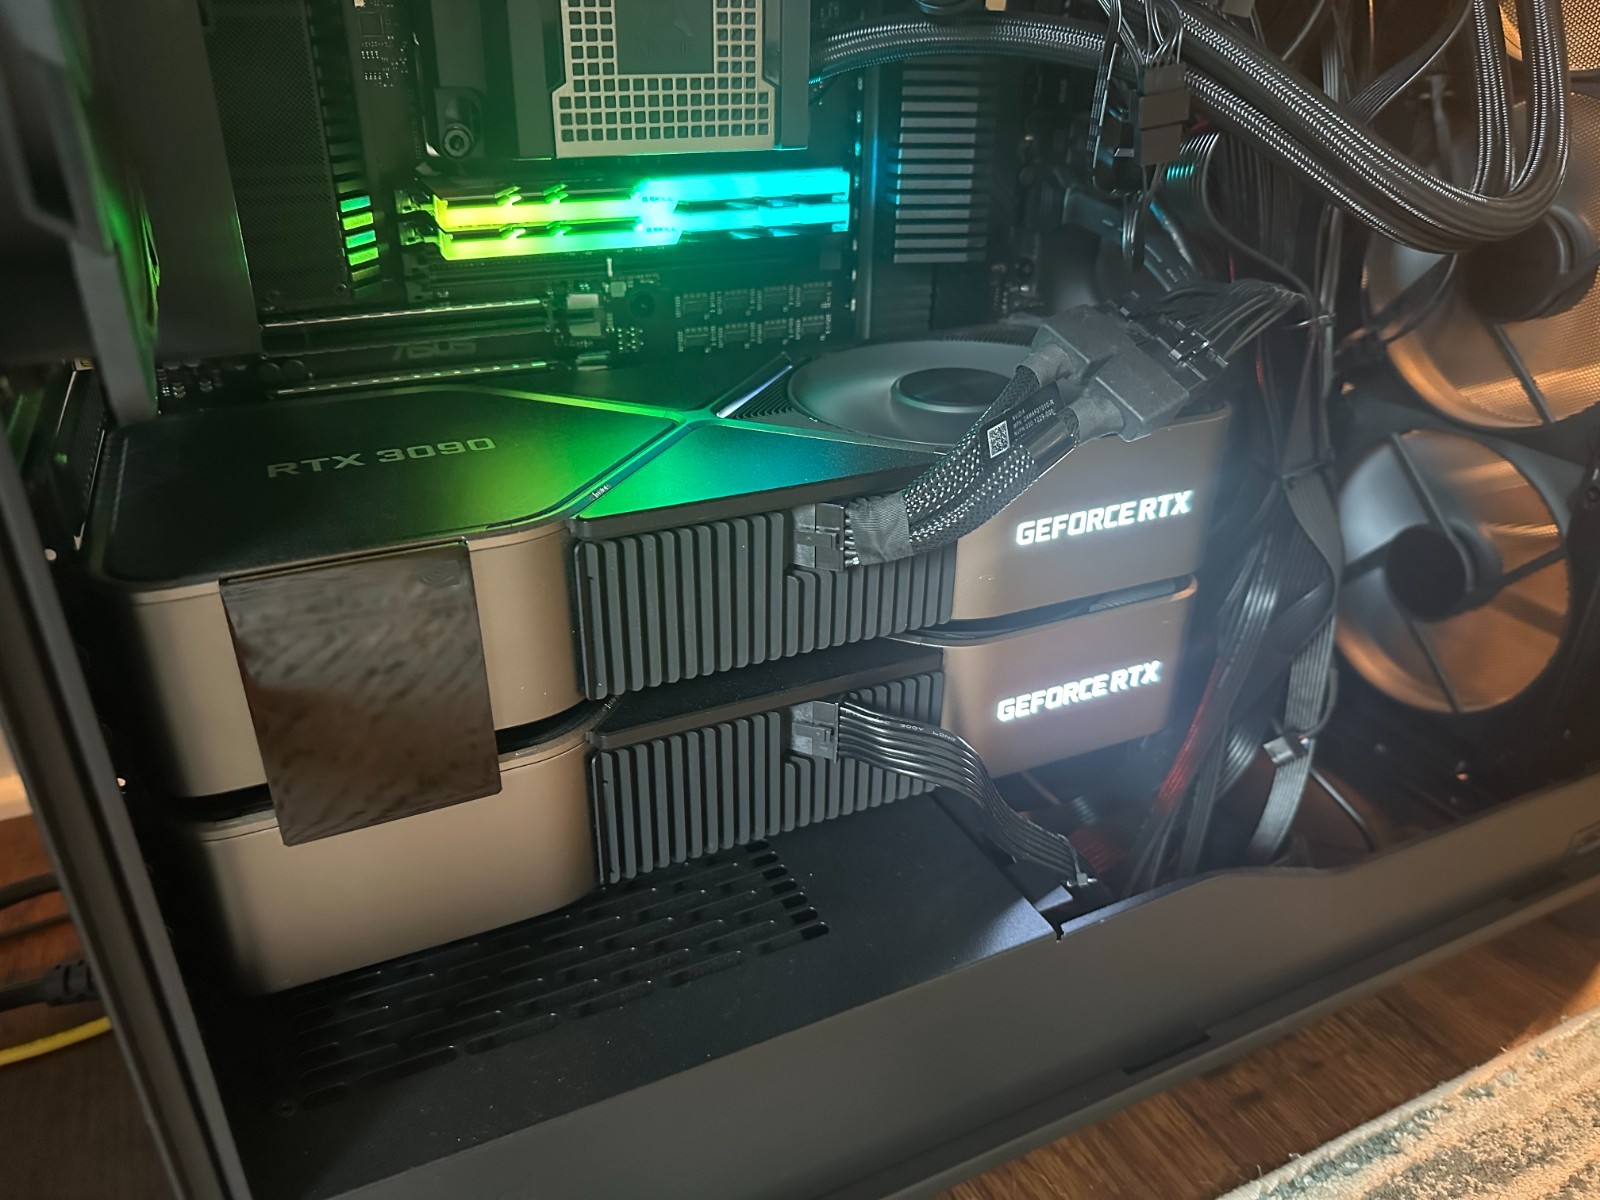
This isn't a gaming PC with two cards bolted in. It's a purpose-built AI inference workstation — assembled with intent, tuned once, and then simply left to do its job. NEVER mined, never overclocked, never run at sustained full load.
WHAT IT ACTUALLY DOES — MEASURED, NOT MARKETING• Serves Gemma 4 31B (4-bit, tensor-parallel over NVLink) with vLLM at ~60 tokens/s, time-to-first-token ~150–250 ms on a 9K-token system prompt.• Runs that PLUS Whisper-large speech-to-text and additional fine-tuned models on the same two GPUs — a real multi-model setup, not a benchmark loop.• Light duty by design: the GPUs sit in P8 idle (15–20 W) most of the day and wake up for short inference bursts. Idles at ~40 °C on the GPUs and ~45 °C on the CPU with the full stack loaded. Zero thermal throttling, zero hardware faults.
WHY IT PUNCHES ABOVE ITS WEIGHT — EVERY PART CHOSEN ON PURPOSE• 2× NVIDIA RTX 3090 Founders Edition + NVLink bridge — the last consumer generation with NVLink. 48 GB of pooled VRAM that actually behaves like one pool for tensor parallelism. Run 30B-class models comfortably, 70B with TP + offload, fine-tune with LoRA/QLoRA.• AMD Threadripper PRO 3955WX (16C/32T) on ASUS Pro WS WRX80E-SAGE SE WIFI II — 128 PCIe 4.0 lanes, so both GPUs get a full x16 and there is still room for 2 more. 7 full-length slots, IPMI remote management (reboot, console, sensors from anywhere), dual 10 GbE onboard, Wi-Fi 6E.• 128 GB DDR4-3600 G.Skill Trident Z RGB (4×32 GB, CL18) with 4 DIMM slots free — go to 256 GB without touching what's there.• be quiet! Power Zone 2 1000W 80+ Platinum, ATX 3.1 — native 12V-2x6, fully modular, near silent. Ready for whatever GPU you drop in next.• ARCTIC Liquid Freezer WS360-SP6 — workstation-class 360 mm AIO with a full-coverage Threadripper cold plate, not a desktop cooler stretched to fit.• Fractal Design Meshify 3 XL — full-tower mesh airflow with dust filters; the reason two 350 W cards sit at 40 °C.• Samsung 990 PRO 1 TB NVMe Gen4 for models and OS.
WHO THIS IS FORAnyone who wants to run open-weight LLMs locally — vLLM, llama.cpp, TensorRT-LLM, Ollama — or fine-tune on their own data, without renting cloud GPUs by the hour. Plug it in, install Ubuntu (or take my clean Ubuntu 24.04 + CUDA 13 install, free), and you're serving models the same evening.
CONDITIONUsed, excellent. Built spring 2026, ~5 months of light-duty use. Never mined, never overclocked. Stress-tested before listing: no artifacts, no throttling. Cleaned before shipping. NVMe securely wiped.
INCLUDED: complete assembled system, NVLink bridge, power cord. No monitor/keyboard.SHIPPING: FREE. Shipped fully assembled — GPUs braced with internal foam inserts, double-boxed, fully insured. Plug in and go. Local pickup in the Charlotte, NC area welcome.RETURNS: No returns — sold exactly as described; fully tested and photographed working before shipping.