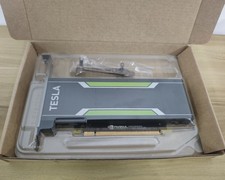
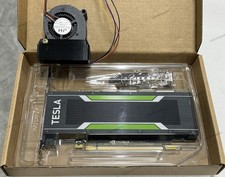
The NVIDIA
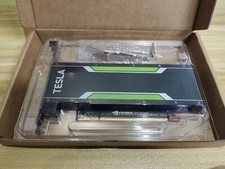
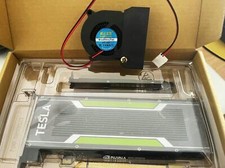
Tesla Referral P4 is powered by the revolutionary NVIDIA Pascal™ architecture andpurpose-built to boost efficiency for scale-out servers running deep learning workloads,enabling smart responsive AI-based services. It slashes inference latency by 15X in anyhyperscale infrastructure and provides an incredible 60X better energy efficiency than CPUs.This unlocks a new wave of AI services previous impossible due to latency limitations.
GPU Architecture - NVIDIA Pascal
Single-Precision Performance - 5.5 TeraFLOPS
Integer Operations (INT8) - 22 TOPS (Tera-Operations per Second)
GPU Memory - 8 GB
CUDA Cores - 2560
Memory Bandwidth - 192 GB/s
System Interface - Low-Profile PCI Express Form Factor
Max Power - 75W
Thermal Solution - Passive Heatsink
Enhanced Programmability with Page Migration Engine - Yes
ECC Protection - Yes
Server-Optimized for Data Center Deployment - Yes
Hardware-Accelerated Video Engine - 1x Decode Engine, 2x Encode Engine
Was used to create Chia plots.
Does not have connections for video output
Will provide half height bracket upon request.